Conversational AI for college ERP data
The problem
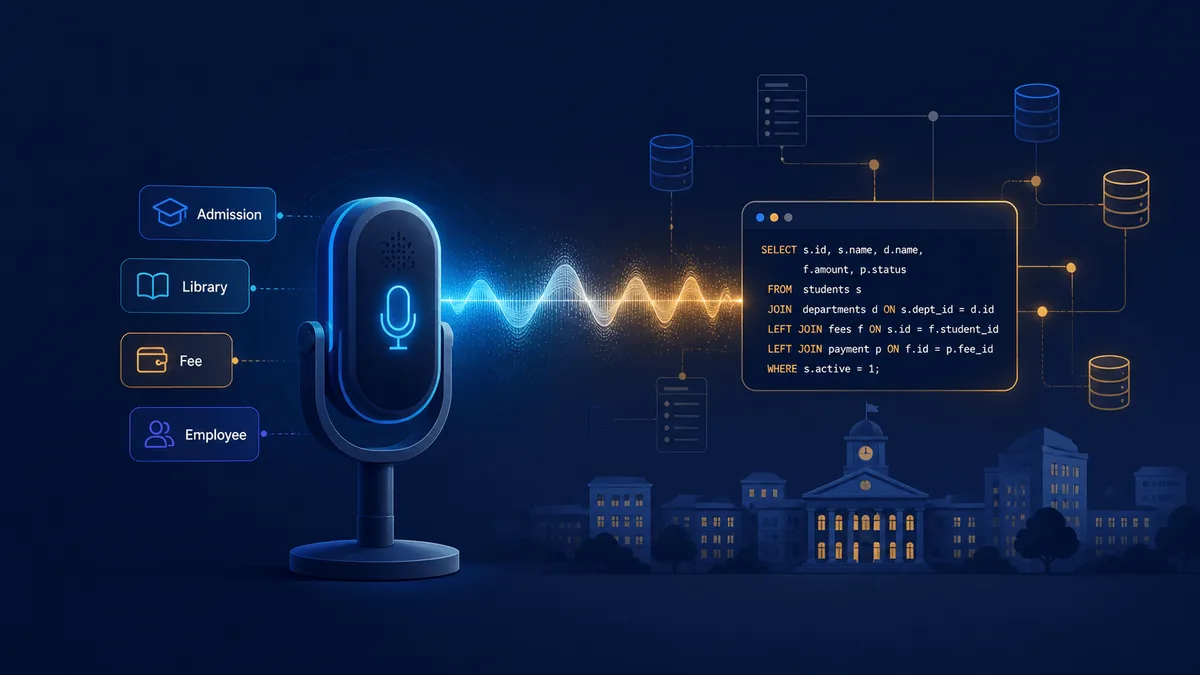
Administrative staff need answers that already exist in an ERP database — fee status, library issues, employee records, admissions — but getting them means knowing which module to open and which report to run. The obvious fix is to let people ask in plain language and generate SQL from it.
The obvious fix is also the dangerous one. A language model emitting raw SQL against a live institutional database puts an unpredictable component directly on the write path of records about real students. The design question is how much of the query the model is allowed to author.
The decision that shapes everything else
The model does not write SQL. It emits fields and conditions as structured JSON, and a deterministic payload builder turns those into the actual query — applying alias mappings, default filters and joins before handing the result to the ERP's own web service, which owns the data and executes against it.
This narrows the blast radius considerably: the model cannot invent a table, a join or a destructive statement, because it never gets to express one. The honest limit is that conditions still travel as SQL fragments, joined and passed through. Prompt instructions are the control there, not a grammar or an allow-list. Closing that gap with an explicit condition grammar is the single change I would make first.
Routing before retrieval, retrieval before generation
A Rasa intent classifier picks the module — student, employee, library, fee — before any retrieval or model call happens. A second Rasa bot disambiguates the genuinely ambiguous case, student versus employee, where the same question shape applies to both.
This ordering is deliberate and it is a cost decision as much as an accuracy one. Classification is fast and cheap; it runs first and narrows what follows. By the time the language model is invoked it sees one module's schema rather than the whole institution's, which makes the generation task smaller and the prompt shorter.
Only then does retrieval run: the question is embedded with a 384-dimension sentence model, schema fields are retrieved from a Milvus collection, and matching few-shot examples are pulled dynamically. Because schema aliases are stored per institution rather than written into prompts, the same pipeline serves several institutions with different column names and no per-institution prompt forks.
Trade-offs I would defend, and one I would not
Structured output over raw SQL — defensible, and described above. The ERP builds the FROM clause and the joins; the model contributes intent, not syntax.
Per-institution alias collections over per-institution prompts — defensible. Adding an institution becomes a data task rather than a prompt-engineering task. The cost is that a schema change needs a collection rebuild, and a stale alias fails quietly rather than loudly.
Exact-match payload caching — not defensible as built. A cache hit requires zero embedding distance, which makes it an exact-match cache wearing a vector database's clothes, and a hit still re-runs against the ERP because result rows are not cached. It is also not keyed by institution. Either key it properly and cache results, or delete it; as it stands it adds a lookup and buys nothing.
Swallowed audit-insert failures — not defensible. Every interaction attempts an audit row, but a failed insert is logged and dropped, so the trail is best-effort. For a system answering questions about student records, the audit trail should be as durable as the answer.
Voice as an output mode, not an architecture
Speech is a client concern. The service exposes transcription, query processing, clarification, module selection and feedback as ordinary HTTP endpoints; synthesized audio is produced where it makes sense and omitted where it does not. Keeping the voice layer at the edge means the whole query pipeline is testable with text and a terminal, which is how it was actually developed.
What is not measured
No latency, accuracy or throughput benchmarks exist for this system, and I will not invent them. The useful next step is a labelled routing set measuring module-classification accuracy, end-to-end latency split by stage, and how often the deterministic payload builder rejects what the model produced — that last number is the real measure of whether the structured-output decision is doing its job.
What this demonstrates
Deciding where a language model's authority ends. The interesting work is the boundary: classification narrows the problem, retrieval grounds it, the model contributes structured intent, and deterministic code — not the model — constructs anything that touches the database.
Client institutions are not named here, and no institutional data appears in this write-up.
Other case studies
Production voice AI for drive-thru ordering · Computer vision attendance with a PTZ camera
Full CV · Download UAE CV (PDF) · Discuss an AI engineering opportunity